August 17, 2026 | General Interest & Animal Behavioral Science
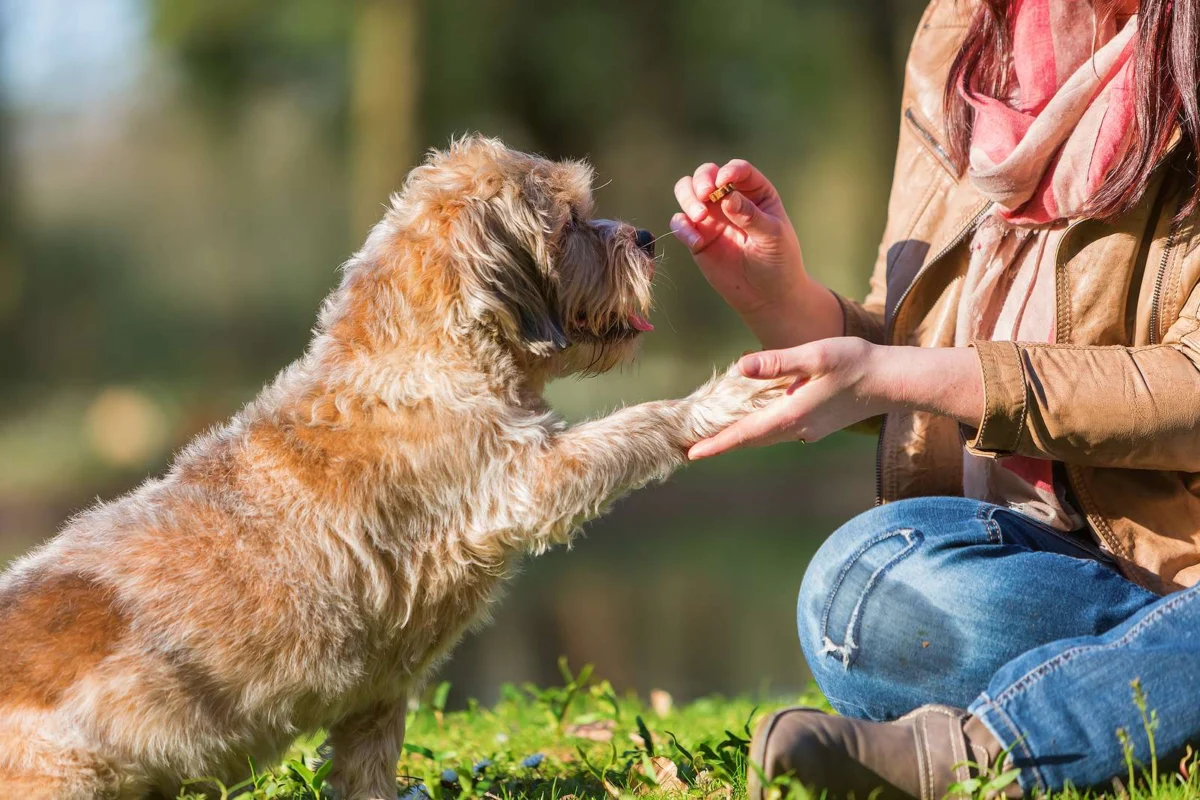
In the traditional landscape of animal training, the pedagogical gold standard has long been defined by volume. Trainers and behaviorists have operated under the assumption that the most effective way to instill a new behavior is through high-repetition sessions, where each successful movement is met with a "micro-reward"—usually a tiny piece of food. The logic has mirrored the structure of a high-intensity gym workout: grind out as many repetitions as possible to build muscle memory.

However, a groundbreaking study published in Science this past May suggests that this "more is better" approach to reward quantity may be fundamentally flawed. By shifting the focus from high-frequency, low-magnitude rewards to high-magnitude, low-frequency "jackpots," researchers have uncovered a more efficient neurobiological pathway to learning.
The Neurobiology of Motivation: Why "Big" Wins
The study, conducted by Gong, Martell, Dudman, and Coddington, challenges the conventional wisdom by demonstrating that the magnitude of a reward significantly dictates the speed and efficacy of learning. According to the research, "very large" rewards—defined as being one to two orders of magnitude larger than standard training treats—led to faster acquisition of skills, higher efficiency in reward collection, and, crucially, a greater ability to remain engaged throughout the task.

At the center of this discovery is dopamine (DA), the neurotransmitter frequently oversimplified as a "pleasure hormone." In reality, as the late neuroscientist Jaak Panksepp famously categorized it, dopamine is the primary driver of "seeking" behavior and motivational salience.
The researchers found that larger rewards triggered a more sustained activation of dopamine neurons during the act of consumption. This sustained neural activity is not merely a momentary flash of pleasure; it acts as a cognitive bridge, allowing the learner to carry the improvements made in one session over to the next. In short, larger rewards are not just "nicer" for the animal—they are biochemically superior tools for teaching.

The "Jackpot" Controversy in Modern Training
For decades, the concept of the "jackpot"—the practice of providing an exceptionally large reinforcement for an especially high-quality performance—has been a point of contention within the canine training community. Critics have long dismissed jackpots as nothing more than "feel-good" anthropomorphism, arguing that there is no empirical data to support the notion that a handful of treats is more effective than the equivalent amount broken into smaller, individual pieces.
Proponents, however, have relied on anecdotal evidence, noting that animals often react to a sudden windfall of rewards with heightened focus and visible enthusiasm. If the research from the Science study holds true for domestic dogs, it suggests that the "jackpot" is far more than a training myth; it is a strategic use of dopamine to reinforce neural pathways more deeply than smaller, frequent rewards ever could.

Implications for Training Methodology
The implications of this research extend far beyond food-based training. The study identifies three critical components of efficient learning:
- The Learning Rate: How quickly the animal associates a behavior with a positive outcome.
- Prior Session Capture: The ability to retain and utilize progress from previous training sessions.
- Sustained Engagement: The capacity to maintain interest and focus without becoming fatigued or distracted.
By utilizing larger, infrequent rewards, trainers may be able to maximize all three aspects. Furthermore, this research invites us to re-examine non-food-based reinforcement. For instance, in the world of high-level Border Collie training, the "long outrun and fetch"—a complex, exhilarating sequence—is often treated as the ultimate reward. Is this, in essence, a behavioral "jackpot"? If the research is accurate, the answer is likely yes. By allowing the dog to engage in a complex, fulfilling task without constant micro-corrections, the trainer may be facilitating a massive, sustained dopamine release that solidifies the behavior far more effectively than constant, small-scale feedback.

A Call for Canine-Specific Replication
While the Science study offers a compelling case for the efficacy of large rewards, it was conducted using mice. The scientific community and professional trainers alike are now tasked with the next logical step: replicating these findings in canine subjects.
The potential for a landmark PhD dissertation or clinical study is clear. If we can confirm that the "dopamine dump" associated with large, well-timed rewards works similarly in dogs, it could revolutionize training protocols, moving the industry away from repetitive, low-reward drilling and toward a more efficient, dopamine-optimized approach.

Reflections from the Field: A Summer Interlude
While the science of motivation continues to evolve, the application of these principles remains a deeply human experience—one best reflected in the time spent away from the lab and the training field. This past August, a much-needed respite in Michigan provided a backdrop for reflecting on the importance of "rewarding" experiences in our own lives.
The Geography of "Great Water"
The trip was anchored by the immense presence of Lake Michigan, known in its original Ojibwe as Michigami. The name, meaning "great water," or, more colloquially, a "REALLY large body of water," served as a reminder of the scale of the natural world. Our transit across this massive basin via the USS Badger—a ferry that feels like a portal to 1959—and the modern Lake Express provided a study in contrasts, much like the debate between traditional, repetitive training and the sudden, high-magnitude "jackpot" approach.

Moments of Connection
Travel, like training, is defined by the quality of the engagement. Whether it was witnessing young men leaping from the Petoskey Breakwall—an act of pure, unadulterated joy that nearly tempted me to toss my cane aside—or visiting with colleagues like Kelly Elvin of Tip Top Tails Dog Training, the trip reinforced the value of sustained, high-quality engagement.
Our time in South Haven, touring the marina aboard the Lindy Lou, offered a glimpse into history. The Lindy Lou, a fan-tailed river launch, once ferried passengers to the dance halls and resorts of a bygone era. It served as a poignant reminder that, just as we must learn how to best reward our animals for their hard work, we must also ensure we are creating "jackpot" moments for ourselves—periods of rest, connection, and joy that break up the repetitive, high-frequency demands of daily life.

Closing Thoughts
As we return to our routines, the question of reward magnitude remains open. Do you use jackpots in your training? Have you observed a shift in your animal’s engagement when you deviate from the "micro-treat" method?
The data suggests that we should be bolder with our rewards, more strategic with our dopamine management, and perhaps, a bit more willing to let our animals—and ourselves—enjoy the occasional, massive payout for a job well done. I look forward to hearing your experiences and observations on this fascinating intersection of neuroscience and behavior.

References:
Gong, Martell, Dudman, & Coddington (2026). "Reward Magnitude and the Neurobiology of Sustained Learning." Science.
(Note: For those interested in the full data set, I encourage you to seek out the full article, as my current access is limited to the public summary. If you are an academic with institutional access, please feel free to share your insights.)